The volume is not the problem
One standing alarm in our own test estate fired more than 4,500 times in 36 days. Nobody is reading those. The point is knowing which of the day's signals is the one that matters.
 TakhitechSOFTWARE
Sightline PLATFORM
Sightline takes the signals from your panels, cameras, UPS, generators, cooling, power and compute, handles what it can on its own, and walks the operator step by step through whatever is left.
A hall generates millions of signals a day. Your panel raises them, your BMS raises them, your cameras raise them, and every one of those systems stops at the same place: somebody now has to know what to do. At 02:00 on a Saturday, that knowledge is usually in one engineer's head rather than in anything you can hand to the person on shift.
One standing alarm in our own test estate fired more than 4,500 times in 36 days. Nobody is reading those. The point is knowing which of the day's signals is the one that matters.
Acknowledgement procedures tend to exist in someone's head rather than in a document. That works until the person who has it is asleep, on leave, or no longer employed.
A DVR, a BMS, a DCIM dashboard, the panel software and a paper runbook, with the actual coordination happening somewhere nobody can audit afterwards.
Sightline sits above the systems you already run rather than replacing them. It takes everything they produce, works the events it is allowed to work, and puts what is left in front of an operator with the procedure attached.
Every panel, camera, rack, sensor and server is normalised into the same site, hall, row, rack and device hierarchy. An event therefore carries its exact location and what sits next to it.
Suppression and de-duplication run before anything reaches a human, and every suppression carries an expiry so a maintenance window cannot quietly become a blind spot. What is left is ranked by severity and by the clock already running on it.
Each event type carries its own response plan. The operator answers one question at a time. Each answer branches the workflow and is written to the record.
The operator gets a procedure for this event, at this site, with the right people to call in the right order. Each step shows the instruction, the evidence and the contact list together, and each answer moves the workflow on, escalating, dispatching or closing as it goes. Nobody writes a runbook and nobody learns an editor. It is built from configuration that already exists, so it is there the first time an operator logs in.
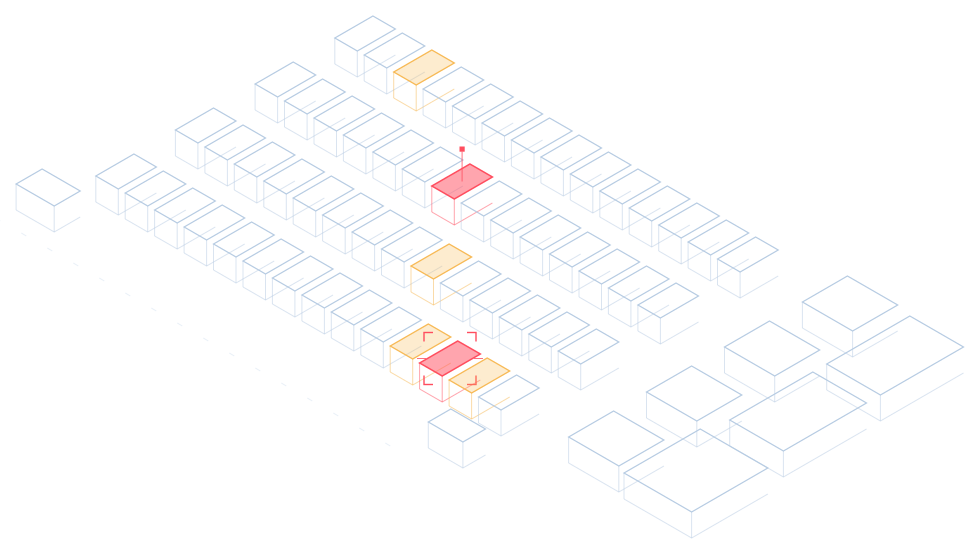
The site model is generated from the same hierarchy that drives your alarms, so there is no separate drawing to maintain. Rows, racks, CRAC units, UPS and the generator yard are laid out live and colour-coded by state. Click anything to open it.
Layout is derived from the site hierarchy, with optional floor-plan image overlay and geofence data. A new row appears in the view once it exists in the system.
Switch the floor between alarm status, thermal gradient, power draw per rack and security state.
Every rack, door and aisle is linked to the cameras covering it. Clicking a location in alarm opens the live feed and the clip from the moment it tripped.
The measure that matters is not how many signals a system can take in. It is how few of them end up costing an operator their attention, and whether you can see that number at all.
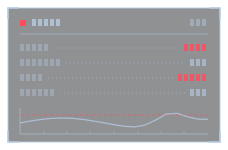
Example reporting view. Figures are illustrative of a single 30 day period in a test estate, not a performance claim about your site.
Every site keeps its own contacts, its own escalation tree and its own procedures, while the queue, the reporting and the audit trail run across all of them. Adding a site does not mean rebuilding how it is handled.
The data centre runs Sightline for its own estate, with its own operators on shift. On-premise inside the facility or hosted by us, with the same role-scoped access and the same audit trail either way.
A monitoring centre runs Sightline across several owners' estates at once, each isolated from the others, each with its own procedures and its own reporting. An owner can take this at some sites and run the rest themselves.
Anything with an API, an SNMP agent, a Modbus register or a dry contact can be brought in and normalised into the same event model. A failing fan tray and a forced door are then handled the same way by the same operator.
Zones, areas and modules mapped to physical racks and rooms, with arm/disarm state and test mode.
Live streams, pre/post-event clips auto-attached to the incident, analytics and tamper detection.
Door forced and held-open events, badge history, escort and visitor tracking per cage and aisle.
Load, runtime remaining, battery health and string temperature, self-test results and bypass state.
Fuel level, run hours, coolant, start failures, transfer events and weekly exercise verification.
Per-outlet draw, phase balance, breaker headroom and redundancy loss when an A or B feed drops.
Supply/return temps, compressor and fan status, chilled water flow, humidifier and filter alarms.
Rack-level temperature and humidity, differential pressure, airflow and thermal drift over time.
CPU, RAM, disk, fans, PSU redundancy, IPMI/Redfish health, SMART warnings and OS agents.
Switch and router reachability, port errors, uplink saturation, optic light levels and BGP session state.
Rope and spot sensors under floor and around CRAC units, pinned to their exact position on the plan.
VESDA aspiration levels, detector state, suppression release and abort, and interlock status.
Detection is the straightforward part. These are the capabilities that determine how long an event takes to close.
Runbooks are the thing every operations team knows it should have and almost nobody keeps current. Sightline builds the procedure for this event, at this site, with the right people in the right order, from configuration that already exists. There is no runbook to author and no editor to learn. It is there the first time an operator logs in, which is the whole point: the gap shows up at 02:00 on a Saturday, not during the rollout.
Security events arrive with the clip already cut and attached, 10 seconds before to 20 after. The operator verifies it before anyone is dispatched.
Ordered contact lists per area with role, hours, instructions and duress codes. Failed contacts auto-advance; every attempt is timestamped.
Per-severity acknowledge and resolve timers run visibly on the card, escalate on breach, and roll into client-facing SLA reporting.
Raise a job from the event with the asset, location and evidence pre-filled, dispatch a technician, and track it back to close on the same record.
Standing alarms, chattering points, stale alarms and alarms per operator per hour, measured against established alarm-management practice rather than just charted. You can see which points are wasting the shift.
An auto-composed handover brief: open incidents, suppressed items and their expiry, jobs in flight, and anything the next shift must watch.
Every view, decision, note and command is recorded against the event and the operator. Exportable for ISO 27001, SOC 2, uptime and insurance evidence.
Planned work suppresses the right zones for the right window, with automatic expiry and a visible reminder so nothing stays muted by accident.
Group halls, buildings and regions. Operators see only their scope; customers can be given a read-only view of just their cages.
The same queue and workflow on a phone for the walking tech, with QR scan on a rack to jump straight to its record.
Automate event handling with automation tools, including DAIOS, our automatic engagement AI solution. Events that do not need a person are handled without one, and the ones that do reach an operator with the work already done.
When an event fires, DAIOS engages the right contacts by voice, SMS, chatbot or email, captures their response, and posts the outcome back to the platform. No operator is involved unless one is needed.
Rules decide which events are handled automatically and which go to the queue, by event type, site, area and time of day. Low value signals are absorbed before anyone sees them.
Events that restore within a set window, or that are answered and resolved by a contact, close themselves with the reason and the full exchange written to the record.
Test modes, maintenance windows and planned suppressions run to a schedule and expire on their own, so nothing stays muted after the work is finished.
Automated engagement follows the same ordered contact list an operator would use, advancing when a contact does not answer and recording every attempt.
Anything automation cannot resolve arrives in the operator queue with the engagement history attached, so the operator starts from what has already been tried.